Related Topics:
Procurement Cases Best Practices-
How many watts does an AI server consume
A fully populated AI server rack with eight high-performance GPUs, dual CPUs, networking cards, and storage can easily consume 12-15 kilowatts of continuous power. GPUs for AI ran at 400 watts until 2022, while 2023 state-of-the-art GPUs for generative AI run at 700 watts, and 2024 next-generation chips are expected to run at 1,200 watts. The average power density is anticipated to increase from 36 kilowatts per server rack in 2023 to 50 kilowatts per rack by. The average AI rack costs $3. Sources: Uptime Institute 2020/2024 Surveys, Ramboll US data centers consumed 176 TWh in 2023, representing 4. By 2024, that rose to approximately 183. In 2023, U. This comprehensive guide explores exactly how much electricity data centers use, what drives their enormous energy appetite, and what the future holds as. Global electricity consumption from data centers reached approximately 415 terawatt-hours (TWh) in 2024, representing about 1. This figure is projected to more than double by 2030, reaching between 945 TWh and 1,050 TWh.
[PDF Version]
-
Are the different components of an AI server a large proportion of its overall performance
While traditional servers rely mostly on CPUs, AI servers lean heavily on graphics processing units (GPUs) and similar AI accelerators that are purpose-built to handle modern AI models. That's the job of an AI server—a custom-built system that keeps AI applications fast, scalable, and efficient. These servers require a combination of high-performance hardware components to process large datasets. AI, or artificial intelligence, is changing the way organizations and businesses handle data by incorporating automation of complex calculations, introducing new advanced applications, and fulfilling computational demands like never before. Key hardware components include a multi-GPU motherboard, high-performance CPU, at least 96GB RAM, effective cooling, a robust. From training complex deep learning models to performing real-time inference, the underlying server infrastructure plays a pivotal role in determining the speed, efficiency, and scalability of AI operations. A critical decision for anyone embarking on AI development or deployment is selecting the.
[PDF Version]
-
P40 multi-GPU AI server
We've built a homeserver for AI experiments, featuring 96 GB of VRAM and 448 GB of RAM, with an AMD EPYC 7551P processor. We'll be testing our Tesla P40 GPUs on various LLMs and CNNs to explore their performance capabilities. We'll also share our approach to cooling these GPUs. more Audio tracks. Tesla P40 24GB for possible local AI server build. 0 16x lanes, 4GB decoding, to locally host a 8bit 6B parameter AI chatbot as a personal project. Would. This guide details the configuration steps required to properly set up multiple Tesla P40 GPUs in passthrough mode for Ollama on an Ubuntu 22. 04 VM running on a Proxmox host. Edit your VM configuration file (/etc/pve/qemu-server/YOUR_VM_ID. It runs 30B+ models that gaming GPUs under $200 can't touch. The catch: no display output, no fans, no native FP16, and you'll need a cooling mod. Pre-installed NVIDIA drivers, Linux/Windows support, and flexible CPU–Memory–GPU combinations make it ideal for AI training, inference, rendering, and scientific computing. Equipped with a substantial 24 GB of GDDR5 VRAM, this GPU is an intriguing option for those looking to run local text generation models.
[PDF Version]
-
AI call not connected to server
Call reconnect(failed_only=True) to retry failed servers, or reconnect(failed_only=False) to restart all servers. I have two agents deployed in Azure AI Foundry (Switzerland North), both using a shared GPT-4. 1 model deployment: Agent 1: apples-agent Has an MCP server configured The MCP server exposes one tool: returns the number of apples in my basket Works correctly when invoked directly - returns expected. When I try to setup the connection in the playground it seems to take a long time to connect to the MCP server (if it really is, not sure) and then goes to the page to list the tools and errors out with “Unable to load tools”. MCP Server just has a single function to create a file Server Implementation @Tool(name = "Create File", description = "Create a file with the provided fileName on the file system") public String createFile(String fileName) {. Make sure you call 'connect ()' first. UserError: Server not initialized. Make sure you call 'connect ()' first. · Issue #446 · openai/openai-agents-python /agents/mcp/server.
[PDF Version]
-
The server belongs to AI
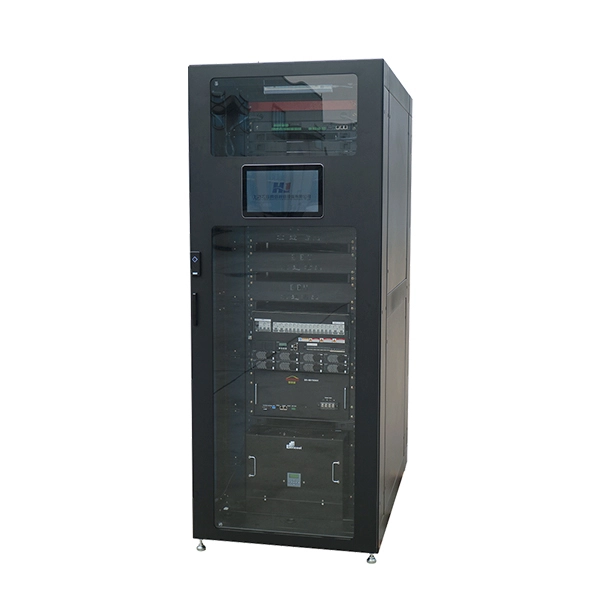
AI servers are high-performance computing systems designed to process complex artificial intelligence workloads, including large-scale model training and real-time inference. Some of these operations involve deep learning, image recognition, and natural language processing. They provide the hardware environment —. Unlike traditional servers designed for general-purpose computing tasks such as hosting websites or managing databases, AI servers are specialised systems engineered to handle the specific computational demands of AI workloads. Deep learning digs through massive data sets to find meaning the way a.
[PDF Version]
-
AI servers surge 20 times
The rapid growth of AI inference services is boosting demand for general-purpose servers, supporting both replacement and expansion efforts. 8%. North American CSPs' continued investments in AI infrastructure are expected to increase global AI server shipments by more than 28% YoY in 2026, according to the latest market research from TrendForce. The expansion in production by TSMC, SK Hynix, Samsung, and Micron has alleviated shortages in the second quarter. This article is a collaborative effort by Bhargs Srivathsan, Marc Sorel, and Pankaj Sachdeva, with Arjita Bhan, Haripreet Batra, Raman Sharma, Rishi Gupta, and Surbhi Choudhary, representing views from McKinsey's Technology, Media & Telecommunications Practice. As challenging as this could be. The global AI Servers Market is poised for significant growth, starting at USD 50. 05 Billion in 2026 and projected to reach USD 558. I need the full data tables, segment breakdown, and competitive landscape for detailed regional analysis and. A comprehensive report by Global Market Insights Inc. 6%, AWS at 16%, and Meta at 10.
[PDF Version]
-
Does AI computing infrastructure require liquid-cooled servers
The next generation of AI servers pushes the bounds of computational power at the cost of increasing power consumption, requiring the use of liquid cooling. Liquid cooling has become a critical enabler for modern AI data centers as facilities scale to handle high-density workloads, such as artificial intelligence (AI) and machine learning. Air is a fundamentally poor thermal conductor. To prevent processors from. At CES 2026, NVIDIA unveiled its next-generation Rubin platform, building on the liquid-cooled Blackwell architecture and designed to operate with warm-water supply loops around 45°C.
[PDF Version]
-
Multi-channel AI Server
In this guide, you'll learn how to architect a Multi-Channel Processing (MCP) server using FastAPI and LangChain. This setup is ideal for projects involving LLMs and AI agents, where performance, modularity, and extensibility matter. 🚀 Why FastAPI + LangChain?OpenClaw is a self-hosted gateway that connects WhatsApp, Telegram, Discord, and iMessage to AI coding agents. You run one Gateway process on your machine, and it becomes the bridge between your messaging apps and an AI assistant you control. OpenClaw installed and running. A configuration file (usually. OpenClaw's multi-agent routing lets you run a whole team of specialized AI agents — each with their own personality, memory, and skills — all from a single server. This. Our stack prioritizes performance, reliability, and scalability, serving as the foundation for teams shipping production-grade autonomous systems.
[PDF Version]
-
Is there a high global demand for AI servers
IDC reports the global server market reached a record $444 billion in 2025. With AI infrastructure remaining a strategic priority, IDC projects AI infrastructure spending will reach $487 billion in 2026 and surpass $1 trillion by 2029. 28 billion by 2034, at a remarkable CAGR of 27. This surge is driven by rising demand for AI applications, advancements in AI technology, cloud and edge computing expansion, and big data analytics. A comprehensive report by Global Market Insights Inc. Explosive enterprise AI adoption and proven return on. The AI Server Market is experiencing robust growth driven by technological advancements and increasing demand for efficient data processing solutions. Energy efficiency has. Soaring demand for AI-ready data centers offers many opportunities for companies and investors across the value chain. How quickly they grasp them could determine the pace at which AI is deployed.
[PDF Version]
-
How many gigabytes is the best optical module
800G optical modules provide 2× bandwidth and ~30–40% better power efficiency per bit than 400G, while reducing fiber count significantly. However, 400G remains more cost-effective for enterprise workloads, and 1. 6T is still in early deployment stages primarily targeting AI-scale. With 400G modules now the baseline, 800G adoption is surging—especially across AI and hyperscaler environments—while 1. 6T modules edge closer to reality. This article unpacks the technologies powering this leap (silicon photonics, advanced modulation, and co-packaged optics), compares deployment. Additionally, 6,720 units of 200G optical modules are needed. The ratio between A100 GPUs and 200G optical modules is 1:6 (1,120 GPUs to 6,720 optical modules). Currently, this specific configuration is not included in the recommended setups. With each generation, they deliver higher data rates, such as 100 Gbps, 400 Gbps, and soon 800 Gbps.
[PDF Version]
-
Which type of cable tray is best for workshops
Each tray type has specific advantages, limitations, and ideal applications: Ladder trays – best for heavy power cables and long runs where airflow is essential. Cable trays support insulated electrical cables in industrial and commercial settings. Unlike conduit systems, cable trays allow cables to be laid in bundles, improving accessibility, heat. A cable tray system is an essential part of modern electrical installations, designed to support, protect, and organize electrical cables efficiently. Learn about ladder, perforated, solid-bottom, wire mesh, and channel trays in this complete guide. A rung spacing of 6 to 9 inches (150 to 230 mm) is preferable when the cable tray cont d for instrumentation and control applications that require.
[PDF Version]
-
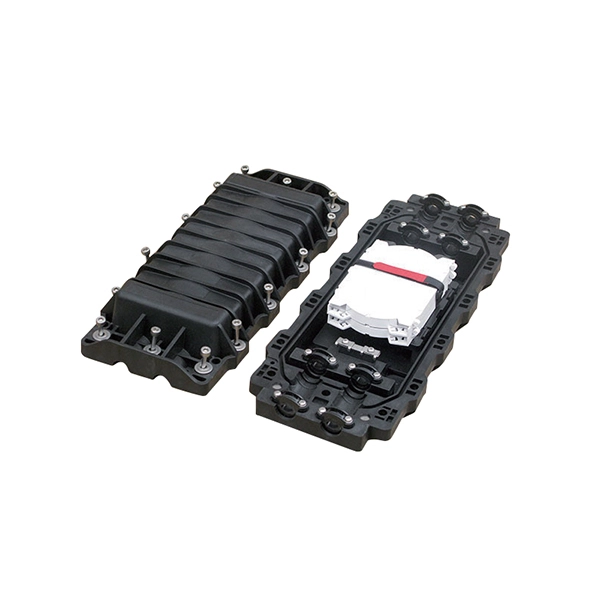
Do fiber optic splice closures use fusion spliced fiber optic cables
When two fiber optic cables need to be joined together, the individual fibers within the cables are carefully aligned and fused together using a specialized fusion splicer. The resulting splice needs to be protected from external elements such as moisture, dust, and physical stress. Closures for FTTH preterminated cables (plug &. This guide reveals the secrets to fusion splicing with little fluff—just proven, straightforward techniques refined from years of work in the field. The guide provides the complete workflow, covering safety precautions, tool selection, fiber preparation, fusion operation, quality control, and. In real fiber optic networks, cables are rarely installed as one continuous, uninterrupted length. Along transmission routes—whether in access networks, metro networks, or backbone infrastructure—fiber cables must be joined, branched, repaired, or reserved for future expansion. Get the wrong connector type, the wrong polish, or skip proper fusion splicing technique—and you're looking at elevated signal loss, increased back reflection, and a. Fiber optic cable splicing involves joining two fiber optic cables together.
[PDF Version]
-
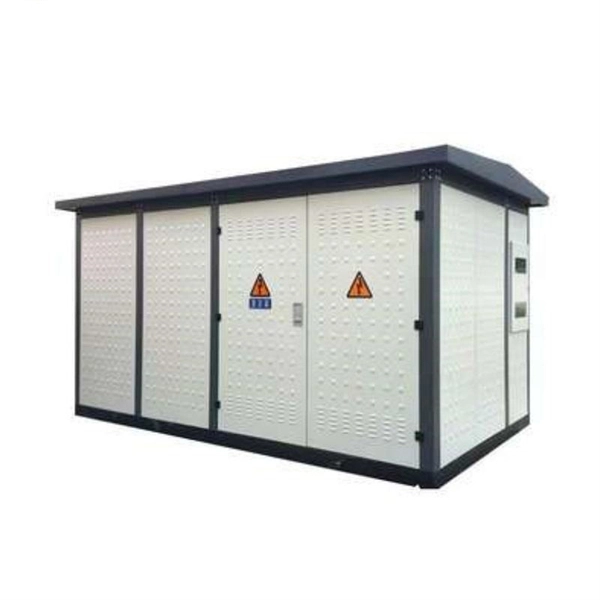
Requirements for the use of secondary distribution boxes
Choose the right box based on environment (indoor/outdoor), load capacity, and durability. Check for proper IP/NEMA ratings and material quality. In this guide, we'll break down everything you need to know to install a distribution box correctly and confidently. Ensure safe placement: install in. This document represents the minimum requirements and specifications for the installation of the electrical underground distribution systems fed from padmounted transformation, serving Secondary Service Accounts, to be transferred to Oncor Electric Delivery Company ownership. REFERENCES This. secondary unit substation is a close-coupled assembly consisting of enclosed primary high voltage equipment, three-phase power transformers, and enclosed secondary low-voltage equipment.
[PDF Version]