Related Topics:
Generative Server Market Research-
How many watts does an AI server consume
A fully populated AI server rack with eight high-performance GPUs, dual CPUs, networking cards, and storage can easily consume 12-15 kilowatts of continuous power. GPUs for AI ran at 400 watts until 2022, while 2023 state-of-the-art GPUs for generative AI run at 700 watts, and 2024 next-generation chips are expected to run at 1,200 watts. The average power density is anticipated to increase from 36 kilowatts per server rack in 2023 to 50 kilowatts per rack by. The average AI rack costs $3. Sources: Uptime Institute 2020/2024 Surveys, Ramboll US data centers consumed 176 TWh in 2023, representing 4. By 2024, that rose to approximately 183. In 2023, U. This comprehensive guide explores exactly how much electricity data centers use, what drives their enormous energy appetite, and what the future holds as. Global electricity consumption from data centers reached approximately 415 terawatt-hours (TWh) in 2024, representing about 1. This figure is projected to more than double by 2030, reaching between 945 TWh and 1,050 TWh.
[PDF Version]
-
P40 multi-GPU AI server
We've built a homeserver for AI experiments, featuring 96 GB of VRAM and 448 GB of RAM, with an AMD EPYC 7551P processor. We'll be testing our Tesla P40 GPUs on various LLMs and CNNs to explore their performance capabilities. We'll also share our approach to cooling these GPUs. more Audio tracks. Tesla P40 24GB for possible local AI server build. 0 16x lanes, 4GB decoding, to locally host a 8bit 6B parameter AI chatbot as a personal project. Would. This guide details the configuration steps required to properly set up multiple Tesla P40 GPUs in passthrough mode for Ollama on an Ubuntu 22. 04 VM running on a Proxmox host. Edit your VM configuration file (/etc/pve/qemu-server/YOUR_VM_ID. It runs 30B+ models that gaming GPUs under $200 can't touch. The catch: no display output, no fans, no native FP16, and you'll need a cooling mod. Pre-installed NVIDIA drivers, Linux/Windows support, and flexible CPU–Memory–GPU combinations make it ideal for AI training, inference, rendering, and scientific computing. Equipped with a substantial 24 GB of GDDR5 VRAM, this GPU is an intriguing option for those looking to run local text generation models.
[PDF Version]
-
The server belongs to AI
AI servers are high-performance computing systems designed to process complex artificial intelligence workloads, including large-scale model training and real-time inference. Some of these operations involve deep learning, image recognition, and natural language processing. They provide the hardware environment —. Unlike traditional servers designed for general-purpose computing tasks such as hosting websites or managing databases, AI servers are specialised systems engineered to handle the specific computational demands of AI workloads. Deep learning digs through massive data sets to find meaning the way a.
[PDF Version]
-
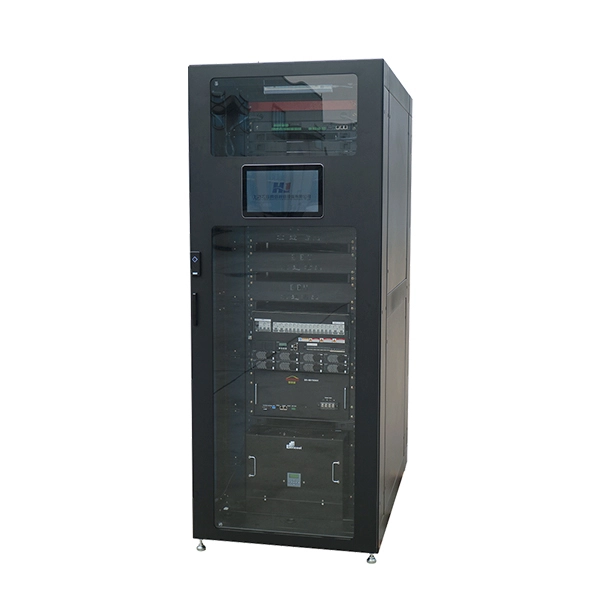
Multi-channel AI Server
In this guide, you'll learn how to architect a Multi-Channel Processing (MCP) server using FastAPI and LangChain. This setup is ideal for projects involving LLMs and AI agents, where performance, modularity, and extensibility matter. 🚀 Why FastAPI + LangChain?OpenClaw is a self-hosted gateway that connects WhatsApp, Telegram, Discord, and iMessage to AI coding agents. You run one Gateway process on your machine, and it becomes the bridge between your messaging apps and an AI assistant you control. OpenClaw installed and running. A configuration file (usually. OpenClaw's multi-agent routing lets you run a whole team of specialized AI agents — each with their own personality, memory, and skills — all from a single server. This. Our stack prioritizes performance, reliability, and scalability, serving as the foundation for teams shipping production-grade autonomous systems.
[PDF Version]
-
Does AI require server configuration
Server needs vary depending on the AI phase: Training: Demands the most resources (high-end GPUs, large RAM). Inference: Requires less power than training, but still needs optimized hardware. Choosing the right AI server setup for your workload is crucial to ensuring optimal performance and scalability. In this comprehensive guide, we will explore the key factors to consider when selecting an AI server setup, including understanding your AI workload requirements, determining the right. AI, or artificial intelligence, is changing the way organizations and businesses handle data by incorporating automation of complex calculations, introducing new advanced applications, and fulfilling computational demands like never before. Role: GPUs are very. A server for local AI inference should not be chosen by the most expensive graphics card, but by whether the model, working cache and parallel requests fit into video memory, and whether the system has enough CPU resources, PCIe lanes, power and cooling. For a small model and a few users, one.
[PDF Version]
-
What are the common network server rack unit counts
What are standard server rack sizes? The most common standard server rack width is 19 inches. Height is measured in rack units (U), with 42U being typical for enterprise deployments. Each of these factors influences equipment fit, airflow management, cable routing. U (rack unit, RU) is a unit of equipment height in a 19" rack. Important: U describes height only, but a server's real "capabilities" are also determined by chassis depth, internal layout, airflow, rails, power, and expansion (PCIe/risers, NVMe. Common server rack sizes are 19‑inch width, heights like 42U or 48U, and depths from ~24″ to 48″. Why Do Rack Sizes Matter? The size of a rack. A Rack Unit (U or RU) is the standard height measurement used for mounting equipment in server racks. 5 inches tall, a 4U device is 7 inches tall, and so on. The “U” standard makes it easy to calculate how many pieces of.
[PDF Version]