Related Topics:
Ultimate Local Chatbot Guide-
AI call not connected to server
Call reconnect(failed_only=True) to retry failed servers, or reconnect(failed_only=False) to restart all servers. I have two agents deployed in Azure AI Foundry (Switzerland North), both using a shared GPT-4. 1 model deployment: Agent 1: apples-agent Has an MCP server configured The MCP server exposes one tool: returns the number of apples in my basket Works correctly when invoked directly - returns expected. When I try to setup the connection in the playground it seems to take a long time to connect to the MCP server (if it really is, not sure) and then goes to the page to list the tools and errors out with “Unable to load tools”. MCP Server just has a single function to create a file Server Implementation @Tool(name = "Create File", description = "Create a file with the provided fileName on the file system") public String createFile(String fileName) {. Make sure you call 'connect ()' first. UserError: Server not initialized. Make sure you call 'connect ()' first. · Issue #446 · openai/openai-agents-python /agents/mcp/server.
[PDF Version]
-
Which country does Huijue AI server belong to
Last month, Huawei unveiled a new AI server cluster in China's Anhui province powered by its in-house Ascend chips, not the dominant GPUs from NVIDIA. This development, alongside reports of performance gains and a growing domestic ecosystem, raises questions about whether US curbs are effectively. Huawei has started reclaiming its growth and influence in Chinese server business due to increasing demands for its AI chips. A few industry analysts reported that Huawei is. Dozens of Chinese hi-tech manufacturers - from Lenovo Group and Huawei Technologies to Inspur Group - are pushing new "all-in-one" servers that include DeepSeek 's advanced artificial intelligence (AI) models to private and public enterprises across the country, ramping up democratisation of the. TOKYO -- Huawei Technologies is steadily building up its own artificial intelligence (AI) infrastructure with homegrown chips and servers, underscoring China's progress on AI development and deployment even under U. We have launched over 220+ cloud services and 210+ solutions.
[PDF Version]
-
P40 multi-GPU AI server
We've built a homeserver for AI experiments, featuring 96 GB of VRAM and 448 GB of RAM, with an AMD EPYC 7551P processor. We'll be testing our Tesla P40 GPUs on various LLMs and CNNs to explore their performance capabilities. We'll also share our approach to cooling these GPUs. more Audio tracks. Tesla P40 24GB for possible local AI server build. 0 16x lanes, 4GB decoding, to locally host a 8bit 6B parameter AI chatbot as a personal project. Would. This guide details the configuration steps required to properly set up multiple Tesla P40 GPUs in passthrough mode for Ollama on an Ubuntu 22. 04 VM running on a Proxmox host. Edit your VM configuration file (/etc/pve/qemu-server/YOUR_VM_ID. It runs 30B+ models that gaming GPUs under $200 can't touch. The catch: no display output, no fans, no native FP16, and you'll need a cooling mod. Pre-installed NVIDIA drivers, Linux/Windows support, and flexible CPU–Memory–GPU combinations make it ideal for AI training, inference, rendering, and scientific computing. Equipped with a substantial 24 GB of GDDR5 VRAM, this GPU is an intriguing option for those looking to run local text generation models.
[PDF Version]
-
Huawei AI Server Liquid Cooling
Huawei developed a full liquid cooling solution, reducing the power consumption by 96% and cutting the PUE from 2. This increase in power density has posed an unprecedented challenge to conventional cooling systems. To address this challenge, Huawei. Advanced AI chips are generating more heat in data centers, necessitating improved cooling solutions. Proposed techniques include circulating water through cold plates, circulating boiling liquid through cold plates. Liquid cooling is essential for AI-driven data centres, efficiently managing the extreme heat generated by high-density AI server racks. It offers up to 15% better energy efficiency and reduces cooling costs compared to traditional air-cooling systems The technology also enables higher server. This AI revolution is built on incredibly powerful computer chips. But there's a catch, a hot one. These chips, especially the GPUs that are the workhorses of AI, are generating a staggering amount of heat.
[PDF Version]
-
Current Status of AI Server Development
Dell, HPE, Lenovo, and Supermicro are riding record AI server demand, but winning enterprise customers requires more than just Nvidia chips. With GPUs standardized around Nvidia, vendors compete on AIOps, liquid cooling, and deployment services as enterprises ramp up inference in 2026. A comprehensive report by Global Market Insights Inc. The market is expected to grow from USD 167. 88 billion in 2024, at a CAGR of 34. This surge is driven by rising demand for AI applications, advancements in AI technology, cloud and edge computing expansion, and big data analytics. The AI server market is projected to reach US$245 billion in 2025 and is expected to grow to US$523 billion by 2030, driven by rising demand for Generative AI (Gen AI) tools like ChatGPT, Perplexity, and Claude, ABI Research said in a report. Enterprises increasingly deploy AI models in-house.
[PDF Version]
-
Multi-channel AI Server
In this guide, you'll learn how to architect a Multi-Channel Processing (MCP) server using FastAPI and LangChain. This setup is ideal for projects involving LLMs and AI agents, where performance, modularity, and extensibility matter. 🚀 Why FastAPI + LangChain?OpenClaw is a self-hosted gateway that connects WhatsApp, Telegram, Discord, and iMessage to AI coding agents. You run one Gateway process on your machine, and it becomes the bridge between your messaging apps and an AI assistant you control. OpenClaw installed and running. A configuration file (usually. OpenClaw's multi-agent routing lets you run a whole team of specialized AI agents — each with their own personality, memory, and skills — all from a single server. This. Our stack prioritizes performance, reliability, and scalability, serving as the foundation for teams shipping production-grade autonomous systems.
[PDF Version]
-
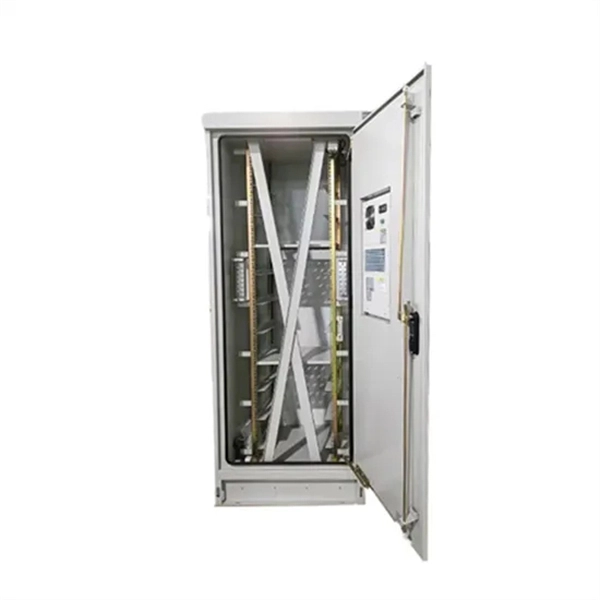
What are the network devices in the server rack
A server rack or network cabinet is designed to accommodate different technical devices, including routers, network switches, hubs, Ethernet cables, patch panels, and other storage devices. A server rack can help well fix many necessary devices into their position to ensure a. Whether in a small server room or a large data center, the rack holds networking, security, storage, and computing equipment in an organized and efficient layout. Understanding these components is essential for managing performance, security, and uptime. It keeps things tidy, improves airflow, and makes it easier to manage and troubleshoot your setup. There are different types of server racks. However, they may also contain routers and switches, storage devices, uninterruptible power supplies (UPSs), and many other types of equipment, often organized according. A good home server rack organizes your hardware, keeps cables under control, and improves airflow.
[PDF Version]
-
Weaknesses in server rack cable management
Poor cable management can cause signal interference, which leads to slower speeds and connection drops. It also enhances airflow, prevents overheating, and minimizes the risk. Organizing server racks and managing cables meticulously is crucial for maintaining a tidy, operational, and dependable data center. By organizing your cables, you reduce downtime during maintenance, improve airflow. Server rack cable management refers to the structured process of organizing, routing, and securing cables within a server rack or cabinet. It ensures that different connections between servers, networking equipment, and power sources remain orderly and accessible. A typical rack environment. Poor cabling practices create more than visual chaos in your server room. According to the ITIC 2024 Hourly Cost of Downtime Report, a single hour of unplanned outage could cost over CAD 300,000 for more than 90% of mid-size and large enterprises.
[PDF Version]
-
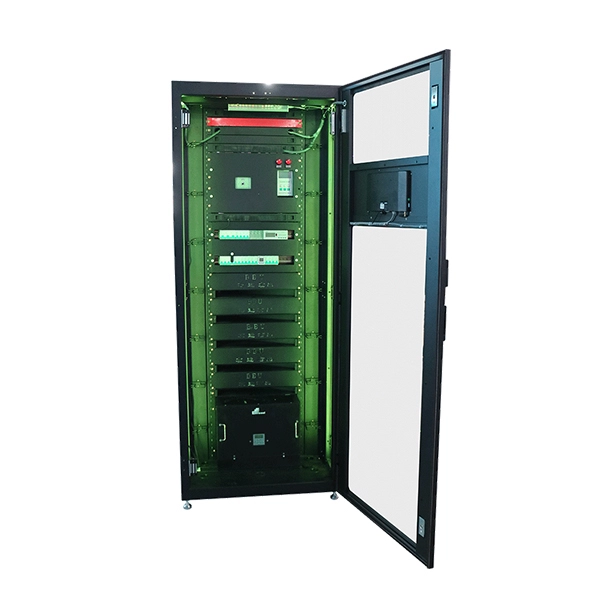
What hardware is included in a network server rack
Network rack parts typically include routers, switches, patch panels, and cable organizers. Whether in a small server room or a large data center, the rack holds networking, security, storage, and computing equipment in an organized and efficient layout. Most have a standard 19-inch width, but they come in various heights and depths. They are generally designed to sit on the floor, but wall-mounted racks may be preferred where. The heart of any structured IT infrastructure is a server rack. Airflow, cable management, mounting hardware, power distribution and many others are all. A good home server rack organizes your hardware, keeps cables under control, and improves airflow. The right components prevent overheating, power issues, and messy wiring. This guide shows you exactly what to install in your rack and how to build a clean, reliable setup at home. It provides efficient cable management, air flow and physical protection for sensitive electronic devices.
[PDF Version]
-
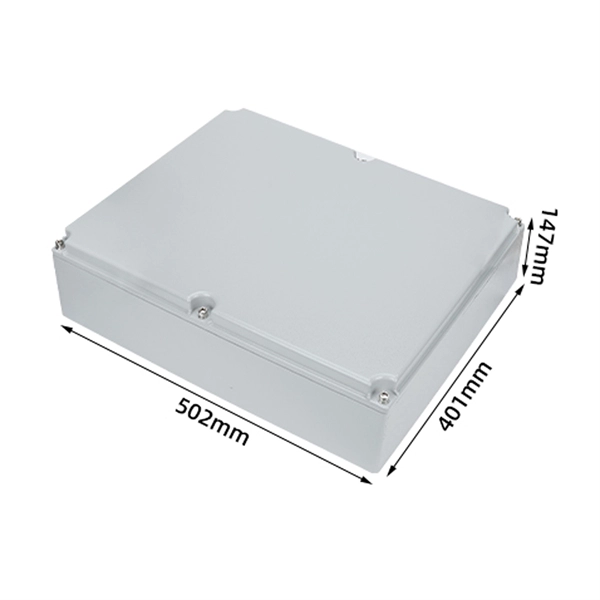
The Role of Optical Modules in Server Racks
Optical modules, the core components enabling optical-electrical conversion, are widely used within data centers. With the continuous evolution of network architectures, the number of optical modules required per server rack has increased significantly. In this paper we review key technological milestones in system embedded optical interconnects in data centers that have been achieved between 2014 and 2020 on major European Union research and development projects. Much of this increase in traffic is dominated by video services. Linear pluggable optics (LPO) is garnering more attention as a way to quickly and efficiently move data in and out of server racks, but a lack of standards for connecting the optical modules is slowing adoption at a time when there is growing pressure to reduce power in data centers.
[PDF Version]
-
What are the common network server rack unit counts
What are standard server rack sizes? The most common standard server rack width is 19 inches. Height is measured in rack units (U), with 42U being typical for enterprise deployments. Each of these factors influences equipment fit, airflow management, cable routing. U (rack unit, RU) is a unit of equipment height in a 19" rack. Important: U describes height only, but a server's real "capabilities" are also determined by chassis depth, internal layout, airflow, rails, power, and expansion (PCIe/risers, NVMe. Common server rack sizes are 19‑inch width, heights like 42U or 48U, and depths from ~24″ to 48″. Why Do Rack Sizes Matter? The size of a rack. A Rack Unit (U or RU) is the standard height measurement used for mounting equipment in server racks. 5 inches tall, a 4U device is 7 inches tall, and so on. The “U” standard makes it easy to calculate how many pieces of.
[PDF Version]